MODERN DATA TECHNOLOGIES IN THE CONSTRUCTION INDUSTRY
26 February 2024
Data Warehouses and Data Lakehouse architecture
26 February 2024

Modern data storage formats and working with Apache Parquet

For data analysis and processing, which includes operations such as filtering, grouping and aggregation, we used Pandas DataFrame, a popular format for working with data, in the examples above. Pandas DataFrame is designed to work efficiently with data in RAM, but it does not have its own data storage format. Therefore, once we are done working with the data, we export the DataFrame to various tabular formats including XLSX and CSV. These formats provide compatibility with external systems, but lack efficiency in terms of stored data size and versioning capability:

  • CSV (Comma-Separated Values): A simple, text-based format widely supported across various platforms and tools. It is straightforward to use but lacks support for complex data types and compression.
  • XLSX (Excel Open XML Spreadsheet): A Microsoft Excel file format that supports complex features like formulas, charts, and styling. While it is convenient for manual data analysis and visualization, it is not optimized for large-scale data processing.

XLSX and CSV are characterized primarily by their widespread use in applications where readability, manual editing, and basic compatibility are required, but they are not optimized for storage and high-performance computing tasks.

There are several popular formats for storing data efficiently, each with unique advantages depending on your specific data storage and analysis requirements:

  • Apache Parquet: A columnar storage file format optimized for use in data analysis systems. It offers efficient data compression and encoding schemes, making it ideal for complex data structures and big data processing.
  • Apache ORC (Optimized Row Columnar): Similar to Parquet, ORC offers high compression and efficient storage. It is optimized for heavy read operations and is well-suited for storing large data lakes.
  • JSON (JavaScript Object Notation): While not as efficient in terms of storage compared to binary formats like Parquet or ORC, JSON is highly accessible and easy to work with, making it ideal for scenarios where human readability and interoperability with web technologies are important.
  • Feather: Feather provides a fast, lightweight, and easy-to-use binary columnar data storage format geared towards analytics. It is designed to efficiently transfer data between Python (Pandas) and R, making it a great choice for projects that involve these programming environments.
  • HDF5 (Hierarchical Data Format version 5): HDF5 is designed to store and organize large amounts of data. It supports a wide variety of data types and is excellent for handling complex data collections. HDF5 is particularly popular in scientific computing for its ability to efficiently store and access large datasets.
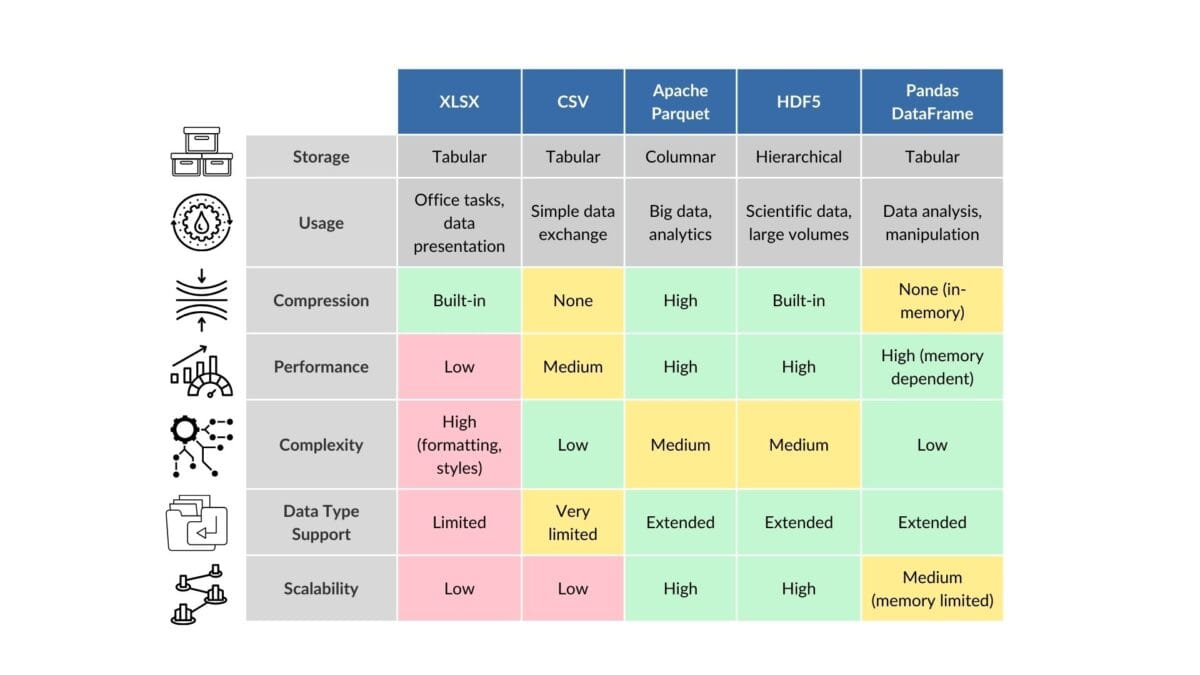
Let's take the Apache Parquet format as an example - it is a freely distributable column-based (Pandas-like) storage format optimized to handle large amounts of data.

Parquet is designed to store data efficiently and compactly compared to traditional relational databases or text-based storage formats such as CSV. Parquet's key features include support for data compression and encoding, which significantly reduces storage size and speeds up data read operations by working directly with the columns you need, rather than all rows of data.

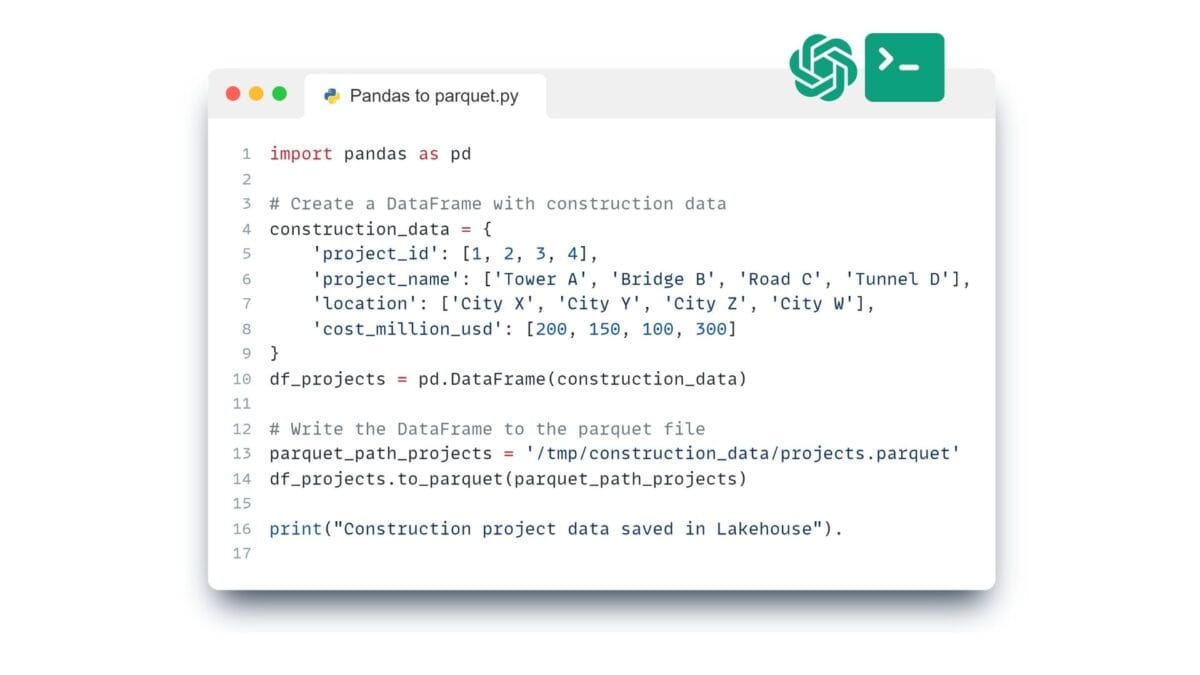
For a visual example of how easy it is to get the necessary code to convert data to Apache Parquet, let's use ChatGPT.

❏ Text request to ChatGPT:

Write code to to save data from Pandas DataFrame to Apache Parquet. ⏎

➤ ChatGPT Answer:
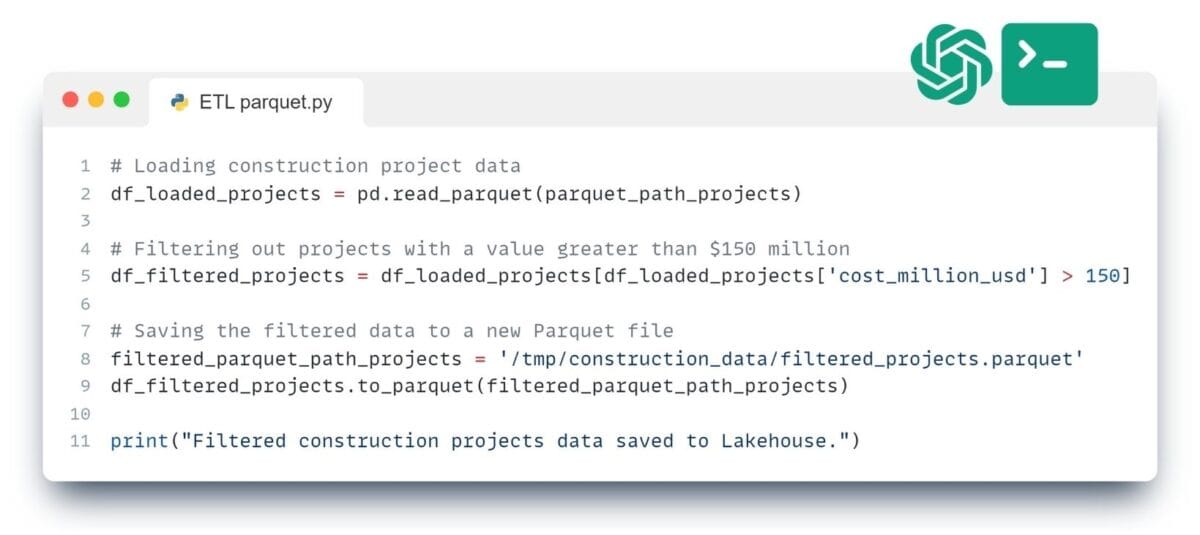
Let's simulate an ETL process with data saved in a format to filter projects by value.

❏ Text request to ChatGPT:

Suppose we want to filter the data and save only those projects that cost more than 150 million dollars. ⏎

➤ ChatGPT Answer:
Designed to provide highly efficient data compression and encoding schemes, the Parquet format significantly reduces storage space and improves the performance of data retrieval operations, making it an ideal choice for both data storage, processing and analytics. It boosts query speed and integrates smoothly with multiple data processing frameworks, enhancing storage, access, and analysis efficiency in these hybrid architectures.

Parquet, a columnar storage file format, excels in managing vast data volumes within Lakehouse models, blending data lakes and warehouses.

Leave a Reply

Change language

Post's Highlights

Stay updated: news and insights


We’re Here to Help

Fresh solutions are released through our social channels

UNLOCK THE POWER OF DATA
 IN CONSTRUCTION

Dive into the world of data-driven construction with this accessible guide, perfect for professionals and novices alike.
From the basics of data management to cutting-edge trends in digital transformation, this book
will be your comprehensive guide to using data in the construction industry.

Related posts 

Focus Areas

Search

Search
Sorry, no articles found.

✕

Don't miss the new solutions


✕
✕

Linux

macOS

Looking for the Linux or MAC version? Send us a quick message using the button below, and we’ll guide you through the process!

✕

📥 Download OnePager

Welcome to DataDrivenConstruction—where data meets innovation in the construction industry. Our One-Pager offers a concise overview of how our data-driven solutions can transform your projects, enhance efficiency, and drive sustainable growth. 

✕

🚀 Welcome to the future of data in construction!

You're taking your first step into the world of open data, working with normalized, structured data—the foundation of data analytics and modern automation tools.

By downloading, you agree to the DataDrivenConstruction terms of use 

Stay ahead with the latest updates on converters, tools, AI, LLM
and data analytics in construction — Subscribe now!

✕

🚀 Welcome to the future of data in construction!

You're taking your first step into the world of open data, working with normalized, structured data—the foundation of data analytics and modern automation tools.

By downloading, you agree to the DataDrivenConstruction terms of use 

Stay ahead with the latest updates on converters, tools, AI, LLM
and data analytics in construction — Subscribe now!

✕

🚀 Welcome to the future of data in construction!

You're taking your first step into the world of open data, working with normalized, structured data—the foundation of data analytics and modern automation tools.

By downloading, you agree to the DDC terms of use 

✕

🚀 Welcome to the future of data in construction!

You're taking your first step into the world of open data, working with normalized, structured data—the foundation of data analytics and modern automation tools.

By downloading, you agree to the DataDrivenConstruction terms of use 

Stay ahead with the latest updates on converters, tools, AI, LLM
and data analytics in construction — Subscribe now!

✕
DataDrivenConstruction offers workshops tested and practiced on global leaders in the construction industry to help your team navigate and leverage the power of data and artificial intelligence in your company's decision making.

Reserve your spot now to rethink your
approach to decision making!

✕


🚀 Welcome to the future of data in construction!

By downloading, you agree to the DataDrivenConstruction terms of use 

Stay ahead with the latest updates on converters, tools, AI, LLM
and data analytics in construction — Subscribe now!

✕
Have a question or need more information? Reach out to us directly!
Schedule a time to discuss your needs with our team.
Tailored sessions to help your team grow — let's plan together!
✕
Have you attended one of our workshops, read our book, or used our solutions? Share your thoughts with us!
Name
✕
Data Maturity Diagnostics

🧰 Data-Driven Readiness Check

This short assessment will help you identify your company's data management pain points and offer solutions to improve project efficiency. It takes only 1–2 minutes to complete and you will receive personalized recommendations tailored to your needs.

✕

Clean & Organized Data

Theoretical Chapters:

Practical Chapters:

What You'll Find on
DDC Solutions:

  • CAD/BIM to spreadsheet/database converters (Revit, AutoCAD, IFC, Microstation)
  • Ready-to-deploy n8n workflows for construction processes
  • ETL pipelines for data synchronization between systems
  • Customizable Python scripts for repetitive tasks
  • Intelligent data validation and error detection
  • Real-time dashboard connectors
  • Automated reporting systems
✕

Connect Everything

Theoretical Chapters:

Practical Chapters:

What You'll Find on
DDC Solutions:

  • CAD/BIM to spreadsheet/database converters (Revit, AutoCAD, IFC, Microstation)
  • Ready-to-deploy n8n workflows for construction processes
  • ETL pipelines for data synchronization between systems
  • Customizable Python scripts for repetitive tasks
  • Intelligent data validation and error detection
  • Real-time dashboard connectors
  • Automated reporting systems
✕

Add AI & LLM Brain

Theoretical Chapters:

Practical Chapters:

What You'll Find on
DDC Solutions:

  • CAD/BIM to spreadsheet/database converters (Revit, AutoCAD, IFC, Microstation)
  • Ready-to-deploy n8n workflows for construction processes
  • ETL pipelines for data synchronization between systems
  • Customizable Python scripts for repetitive tasks
  • Intelligent data validation and error detection
  • Real-time dashboard connectors
  • Automated reporting systems
Modern data storage formats and working with Apache Parquet
This website uses cookies to improve your experience. By using this website you agree to our Data Protection Policy.
Read more
×